A browser-based leather texture workbench connecting on-device classification, Top-3 reference comparison, a specimen archive, and annotated scan records.
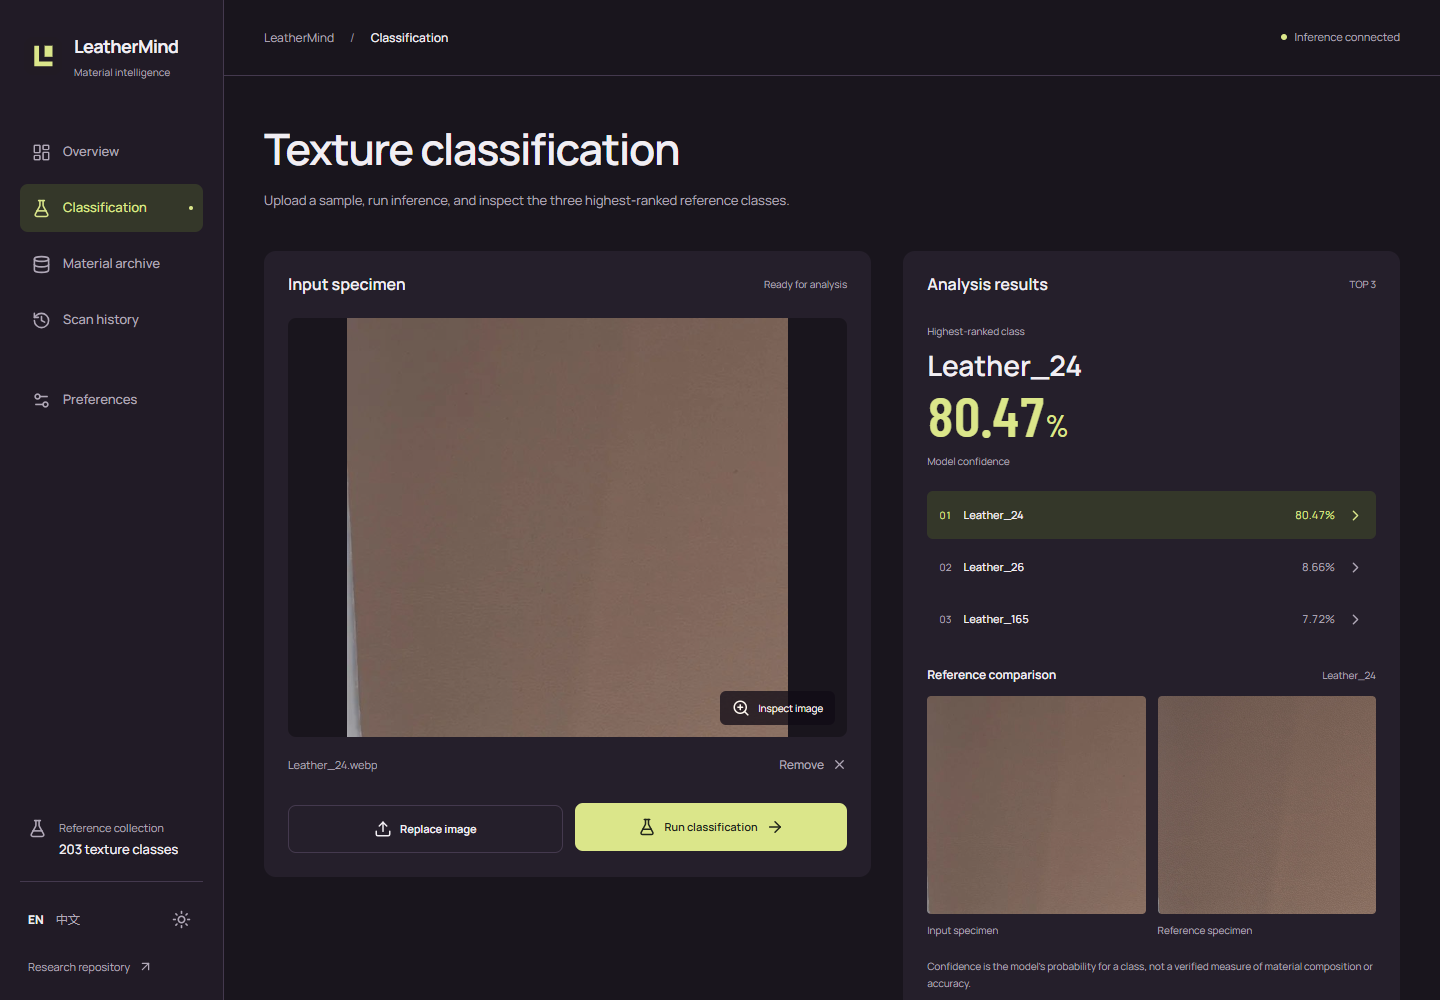
Repository workbench capture using Leather_24, a reference specimen. Confidence shown here is a demo prediction, not a generalization benchmark; the capture is from an earlier verified build.
01 / THE IDEA
A prediction you can look closer at.
A label and confidence score leave much of a texture judgment unexplained. Users need to inspect the original image, see alternatives, compare real reference specimens, and keep their own observations alongside the prediction.
Put the specimen, ranked candidates, and references together. A ResNet50 model runs on the visitor’s device by default, while a searchable archive and scan notes let the user continue beyond the classification result.
02 / THE EXPERIENCE
From start to finish.
01
Capture a specimen
Upload or drag in a JPG, PNG, or WebP, or open the camera and adjust zoom before capturing a single clear texture.
02
Classify on device
Confirm the preview and run classification. First use downloads the model with real byte progress; initialization and inference follow, with cancellation available.
03
Inspect the alternatives
Select among the Top-3 classes to change the reference specimen. Enlarge either image to inspect the texture; the highest-ranked summary remains visible.
04
Keep an observation
Successful results save locally by default. Add notes, reopen a comparison, search history, or export a single result or the collection as JSON.
03 / KEY DECISIONS
The details that shape it.
01
On-device AI has a visible cost
ONNX Runtime Web runs inside a Web Worker with a WASM backend. No inference API key or Python setup is needed in browser mode. The initial model download is substantial, so progress, stages, cancellation, and retry are part of the interaction.
02
Alternatives remain inspectable
Each ranked class opens its associated reference. Choosing the second or third candidate changes the comparison without rewriting the best-match summary. Confidence is explicitly described as a model output, leaving the user room to examine disagreement.
03
The reference collection is a product surface
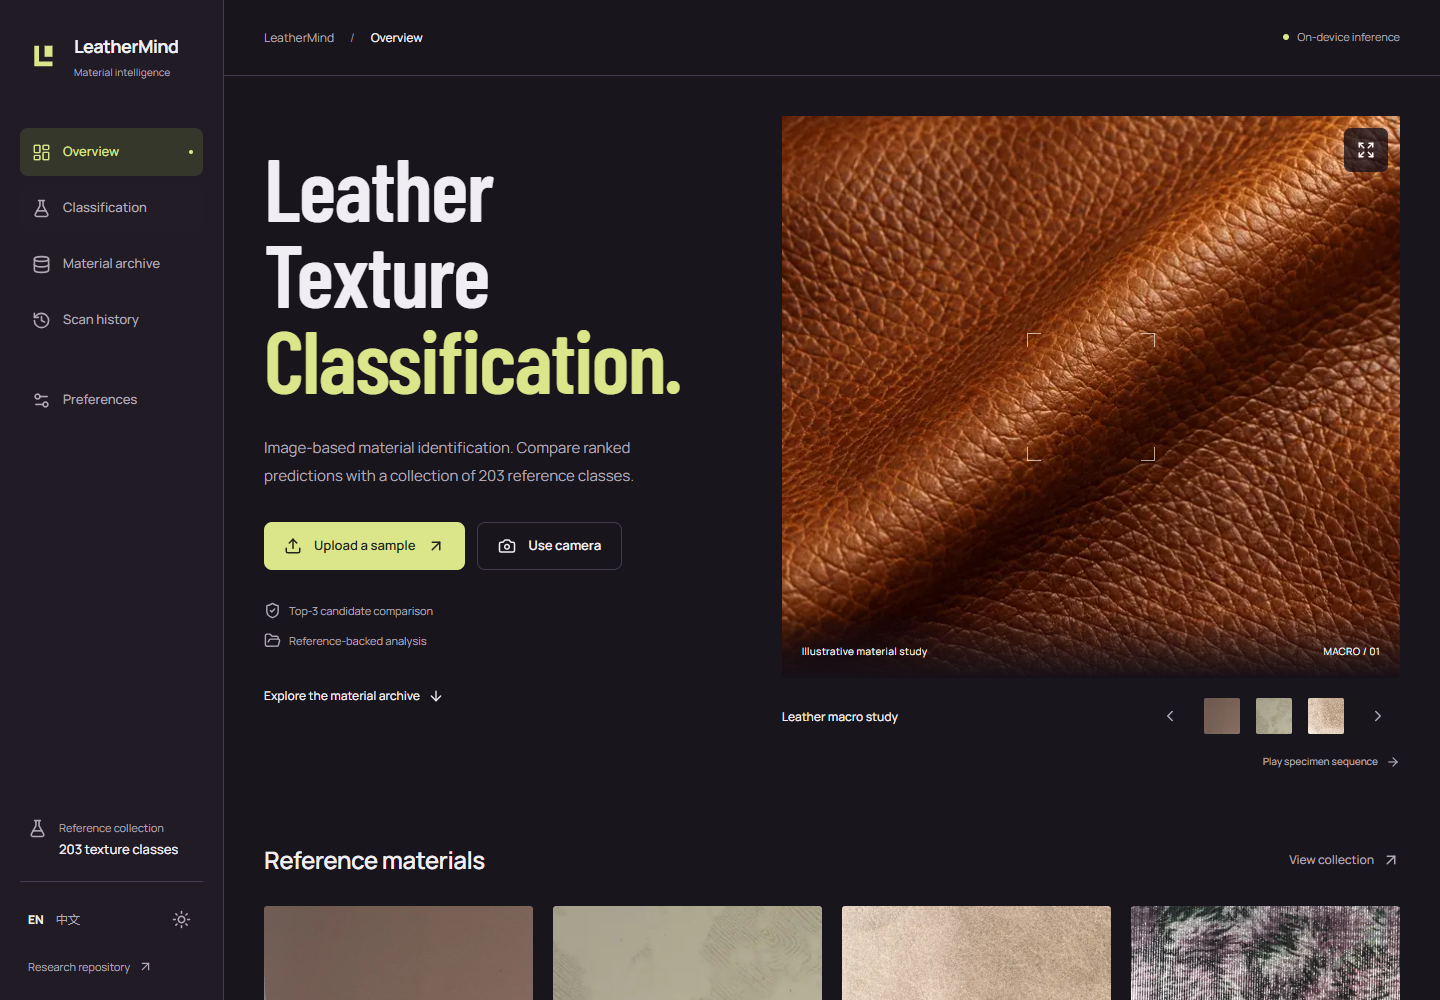
A searchable, paginated archive exposes 203 dataset classes with favorites and enlarged views. Dataset identifiers and image provenance are retained. Illustrative macro imagery on the overview is distinguished from actual dataset references.
04
Prediction and observation stay distinct
Scan history stores the image, candidates, time, and device information. Human notes add an interpretation without changing the predicted label or retraining the model. JSON export gives the record a portable copy.
Repository overview capture. The macro image is illustrative; archive specimens come from the reference dataset.
04 / IMPLEMENTATION
Under the surface.
Browser preprocessing uses antialiased resize to 256, a 224 × 224 center crop, and ImageNet normalization. Ordered class mapping connects the 203 outputs to reference specimens.
A retained conversion report compares PyTorch and ONNX on 203 reference images: Top-1 and ordered Top-3 match for all 203. This checks export equivalence on those images, not independent classification accuracy.
First use downloads roughly 95.6 MB of model data and 14.2 MB of WASM. Caching depends on browser storage; camera capture needs HTTPS and permission.
Classes are dataset identifiers, not verified commercial materials, compositions, or grades. There is no unknown-material rejection flow or published held-out evaluation protocol. Confidence is a model score, not measured real-world accuracy.
Default history remains in this browser, with up to 30 compressed-image records and possible storage reductions. The optional server is a separate mode; browser inference does not silently fall back to the cloud.
How can visual comparison help people question a confident but uncertain prediction?
Project source notes, current README, and retained conversion-validation documentation reviewed on 18 October 2026. No new model evaluation or live camera acceptance test was run.
The question above is a direction for further exploration, rather than a reported research finding.